Whether delivered online or on-site, these instructor-led live Big Data training programs begin with an introduction to fundamental Big Data concepts and advance into the programming languages and methodologies essential for conducting Data Analysis. The course covers tools and infrastructure that enable Big Data storage, Distributed Processing, and Scalability, which are compared and applied through hands-on demo practice sessions.
Big Data training is offered as either "online live training" or "onsite live training". Online live training (also known as "remote live training") utilizes an interactive, remote desktop environment. Onsite live training can be conducted directly at customer premises in Prague or at NobleProg corporate training centers located in Prague.
From Prague Main Train Station (Praha hlavní nádraží)
Take tram 9 from Hlavní nádraží toward Sídliště Řepy.
Get off at Újezd.
Walk about 10 minutes toward Malostranské náměstí / Prokopská.
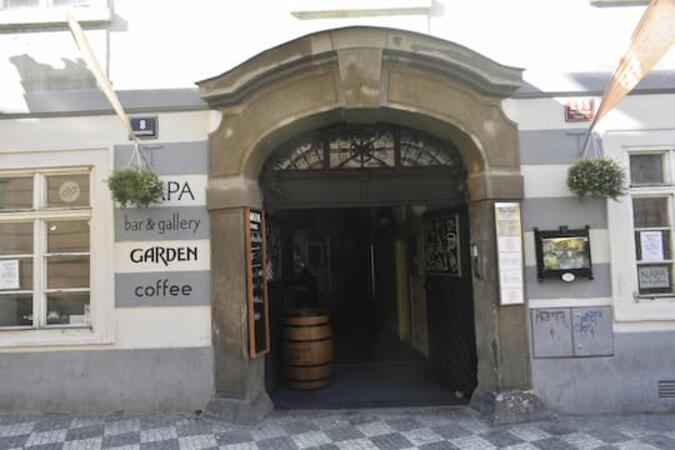
Continue along Prokopská to 296/8.
Alternative: Take the metro C from Hlavní nádraží → Muzeum, change to metro A → Malostranská, then walk across Malá Strana. This involves more walking.
From Prague Bus Station — Florenc
Take metro B from Florenc toward Zličín.
Get off at Můstek.
Change to metro A toward Nemocnice Motol.
Get off at Malostranská.
Walk approximately 10–15 minutes to Prokopská 296/8.
This instructor-led live training in Prague (online or onsite) targets intermediate-level data scientists and engineers who wish to employ Google Colab and Apache Spark for big data processing and analytics.
By the end of this training, participants will be able to:
Set up a big data environment using Google Colab and Spark.
Process and analyze large datasets efficiently with Apache Spark.
Visualize big data in a collaborative environment.
This live, instructor-led training in Prague provides an in-depth look at the Stratio platform, with a specific focus on the Rocket and Intelligence modules powered by PySpark. Participants will develop proficiency in data ingestion, transformation, and advanced analytics, while acquiring practical skills in implementing loops, UDFs, and enterprise-grade data workflows.
This live training in Prague explores core data warehousing concepts, dimensional modeling, and ETL pipeline architecture. Learners will construct star schemas, refine OLAP performance, and apply governance practices to build robust analytical systems.
Participants who complete this instructor-led, live training in Prague will gain a practical, real-world understanding of Big Data and its related technologies, methodologies and tools.
Participants will have the opportunity to put this knowledge into practice through hands-on exercises. Group interaction and instructor feedback make up an important component of the class.
The course starts with an introduction to elemental concepts of Big Data, then progresses into the programming languages and methodologies used to perform Data Analysis. Finally, we discuss the tools and infrastructure that enable Big Data storage, Distributed Processing, and Scalability.
This live training in Prague enables intermediate to advanced users to gain mastery over Greenplum architecture and data modeling. Participants will develop the skills to design distributed tables, execute high-performance SQL, and interpret EXPLAIN plans to achieve optimal query execution in large-scale analytic settings.
This instructor-led session on Prague focuses on the deployment, maintenance, and library management of Greenplum. Attendees will develop the competency to configure clusters, implement safe patching strategies, and manage extensions for advanced analytics, gaining practical skills applicable to real-world operational environments.
This instructor-led, live training in Prague (online or onsite) is aimed at advanced-level data professionals who wish to optimize data processing workflows, ensure data integrity, and implement robust data lakehouse solutions that can handle the complexities of modern big data applications.
By the end of this training, participants will be able to:
Gain an in-depth understanding of Iceberg’s architecture, including metadata management and file layout.
Configure Iceberg for optimal performance in various environments and integrate it with multiple data processing engines.
This instructor-led, live training in Prague (online or onsite) is aimed at beginner-level data professionals who wish to acquire the knowledge and skills necessary to effectively utilize Apache Iceberg for managing large-scale datasets, ensuring data integrity, and optimizing data processing workflows.
By the end of this training, participants will be able to:
Gain a thorough understanding of Apache Iceberg's architecture, features, and benefits.
Learn about table formats, partitioning, schema evolution, and time travel capabilities.
Install and configure Apache Iceberg in different environments.
Create, manage, and manipulate of Iceberg tables.
Understand the process of migrating data from other table formats to Iceberg.
This instructor-led, live training in Prague (online or onsite) is aimed at intermediate-level IT professionals who wish to enhance their skills in data architecture, governance, cloud computing, and big data technologies to effectively manage and analyze large datasets for data migration within their organizations.
By the end of this training, participants will be able to:
Understand the foundational concepts and components of various data architectures.
Gain a comprehensive understanding of data governance principles and their importance in regulatory environments.
Implement and manage data governance frameworks such as Dama and Togaf.
Leverage cloud platforms for efficient data storage, processing, and management.
This instructor-led, live training in Prague (online or onsite) is aimed at intermediate-level data engineers who wish to learn how to use Azure Data Lake Storage Gen2 for effective data analytics solutions.
By the end of this training, participants will be able to:
Understand the architecture and key features of Azure Data Lake Storage Gen2.
Optimize data storage and access for cost and performance.
Integrate Azure Data Lake Storage Gen2 with other Azure services for analytics and data processing.
Develop solutions using the Azure Data Lake Storage Gen2 API.
Troubleshoot common issues and optimize storage strategies.
This instructor-led, live training in Prague (online or onsite) is aimed at developers who wish to use and integrate Spark, Hadoop, and Python to process, analyze, and transform large and complex data sets.
By the end of this training, participants will be able to:
Set up the necessary environment to start processing big data with Spark, Hadoop, and Python.
Understand the features, core components, and architecture of Spark and Hadoop.
Learn how to integrate Spark, Hadoop, and Python for big data processing.
Explore the tools in the Spark ecosystem (Spark MlLib, Spark Streaming, Kafka, Sqoop, Kafka, and Flume).
Build collaborative filtering recommendation systems similar to Netflix, YouTube, Amazon, Spotify, and Google.
Use Apache Mahout to scale machine learning algorithms.
This instructor-led live training in Prague explores advanced big data techniques, distributed computing, and machine learning at scale. It is designed for advanced data professionals aiming to master real-time analytics, deep learning integration, and robust data governance strategies.
This instructor-led live training in Prague (online or onsite) is targeted at intermediate-level IT professionals who desire a comprehensive grasp of IBM DataStage from both administrative and development perspectives, enabling them to effectively manage and utilize this tool in their workplaces.
By the end of this training, participants will be able to:
Understand the core concepts of DataStage.
Learn how to effectively install, configure, and manage DataStage environments.
Connect to various data sources and extract data efficiently from databases, flat files, and external sources.
This instructor-led live training, conducted in Prague (either online or onsite), targets system administrators at the beginner to intermediate level who intend to deploy, maintain, and optimize Spark clusters.
Once completed, participants will be capable of:
Setting up and configuring Apache Spark in diverse environments.
Managing cluster resources and monitoring Spark applications.
Improving the performance of Spark clusters.
Applying security measures and ensuring high availability.
Debugging and fixing common Spark-related problems.
In this instructor-led, live training held in Prague, participants will explore how to combine Python and Spark for big data analysis through a series of practical, hands-on exercises.
By the conclusion of the training, participants will be able to:
Analyze Big Data by integrating Spark with Python.
Solve exercises modeled after real-world use cases.
Leverage diverse tools and techniques for big data analysis using PySpark.
Explore Big Data BI for government agencies in Prague. This course covers Hadoop, NoSQL, predictive analytics, and real-time tools for managing vast, diverse data streams. Learn fraud detection, cybersecurity, and ROI strategies to transform unstructured data into strategic assets for mission success.
During this instructor-led, live training in Prague, participants will cultivate the mindset necessary to approach Big Data technologies, assess their impact on existing processes and policies, and implement these technologies to identify criminal activity and prevent crime. We will analyze case studies from law enforcement organizations worldwide to gain insights into their adoption approaches, challenges, and results.
By the end of this training, participants will be able to:
Combine Big Data technology with traditional data gathering processes to piece together a story during an investigation.
Implement industrial big data storage and processing solutions for data analysis.
Prepare a proposal for the adoption of the most adequate tools and processes for enabling a data-driven approach to criminal investigation.
Discover the core principles of handling Big Data using R, a language highly regarded in the finance industry. This module in Prague guides you through environment configuration, leveraging MPI for parallel computing, and working with distributed matrices. You will gain the skills to manage large-scale datasets, execute distributed regression analyses, and implement Monte Carlo methods with greater efficiency.
This instructor-led live training (online or onsite) is designed for data engineers, analysts, and professionals who wish to use Databricks and PySpark to build scalable data pipelines and migrate existing SQL workflows.
In Prague, this five-day training explores real-time data streaming systems. It addresses core concepts, architectural patterns, and industry tools for processing continuous data at scale. Participants will learn to design, implement, and optimize scalable streaming pipelines using modern frameworks.
This instructor-led live training in Prague is tailored for intermediate administrators seeking to deploy and oversee Apache NiFi in production settings. Participants will master cluster configuration, dataflow design, and performance optimization through hands-on labs and scenario-based practical exercises.
This training offers a hands-on introduction to developing scalable data processing and Machine Learning workflows with PySpark. Participants will gain insight into how Apache Spark functions within contemporary Big Data ecosystems and learn to process large datasets efficiently by leveraging distributed computing principles.
This intensive three-day practical course is dedicated to designing and tuning high-performance data-processing workloads within Kubernetes environments, utilising PySpark, Pandas and Polars.
Learners will gain a working knowledge of how Spark applications are executed on Kubernetes and how application-level configuration choices directly impact performance, scalability, resource utilisation and overall cost. Key optimisation topics covered include executor sizing, memory management, dynamic allocation, partitioning methods, shuffle mechanics, the challenge of small files and the efficient handling of Parquet data.
The curriculum also tackles common pain points associated with Pandas, such as memory constraints and out-of-memory errors, while introducing Polars as a high-speed alternative for specific data-processing tasks. Through practical, hands-on exercises, participants will learn to diagnose performance and memory issues, evaluate various configuration strategies and implement optimisation techniques in realistic ETL and machine learning contexts.
The course prioritises practical decision-making, focusing on how to pinpoint bottlenecks, choose the right tools, configure Spark effectively and strike a balance between high performance and responsible infrastructure resource usage and cost management.
This instructor-led live training in Prague (online or onsite) is aimed at engineers who wish to set up and deploy an Apache Spark system for processing very large amounts of data.
By the end of this training, participants will be able to:
Install and configure Apache Spark.
Quickly process and analyze very large data sets.
Understand the difference between Apache Spark and Hadoop MapReduce and when to use which.
Integrate Apache Spark with other machine learning tools.
This hands-on training in Prague simplifies Apache Spark concepts, covering RDDs, DataFrames, and the Python/Scala APIs. Participants will gain mastery in cloud deployment using Databricks, AWS EMR, and Glue, equipping themselves with practical skills tailored for real-world data engineering and DevOps scenarios.
This instructor-led live training in Prague (online or on-site) is aimed at technical professionals who wish to deploy Talend Open Studio for Big Data to simplify the process of reading and analyzing Big Data.
By the end of this training, participants will be able to:
Install and configure Talend Open Studio for Big Data.
Connect with Big Data systems such as Cloudera, HortonWorks, MapR, Amazon EMR, and Apache.
Understand and set up Big Data components and connectors within Open Studio.
Configure parameters to automatically generate MapReduce code.
Use Open Studio's drag-and-drop interface to run Hadoop jobs.
Prototype Big Data pipelines.
Automate Big Data integration projects.
Read more...
Last Updated:
Testimonials (7)
A journey through the Spark world: a very intense course. DSL, spark sql, partitioning vs bucketing for me.
Georgiana Elisabeta
Course - Apache Spark Fundamentals
the practices
Liliana Padilla - Hipodromo de Agua Caliente
Course - Greenplum Architecture and Data Modeling
Hands on exercises. Class should have been 5 days, but the 3 days helped to clear up a lot of questions that I had from working with NiFi already
James - BHG Financial
Course - Apache NiFi for Administrators
The ability of the trainer to align the course with the requirements of the organization other than just providing the course for the sake of delivering it.
Masilonyane - Revenue Services Lesotho
Course - Big Data Business Intelligence for Govt. Agencies
The fact that we were able to take with us most of the information/course/presentation/exercises done, so that we can look over them and perhaps redo what we didint understand first time or improve what we already did.
Raul Mihail Rat - Accenture Industrial SS
Course - Python, Spark, and Hadoop for Big Data
Having hands on session / assignments
Poornima Chenthamarakshan - Intelligent Medical Objects
Course - Apache Spark in the Cloud
The subject matter and the pace were perfect.
Tim - Ottawa Research and Development Center, Science Technology Branch, Agriculture and Agri-Food Canada
Online Big Data training in Prague, Big Data training courses in Prague, Weekend Big Data courses in Prague, Evening Big Data training in Prague, Big Data instructor-led in Prague, Big Data trainer in Prague, Big Data instructor-led in Prague, Big Data one on one training in Prague, Weekend Big Data training in Prague, Big Data boot camp in Prague, Big Data private courses in Prague, Big Data on-site in Prague, Big Data instructor in Prague, Big Data classes in Prague, Online Big Data training in Prague, Big Data coaching in Prague, Evening Big Data courses in Prague